Introduction
Imagine an e-commerce company preparing its daily sales report.
Its data pipeline successfully collects transactions, processes millions of records, and loads the results into the data warehouse. Every task shows green, no errors are reported, and the pipeline finishes on time.
But the finance team discovers that daily revenue is 8% higher than expected.
The reason? An upstream system sent duplicate order IDs during an API failure. The pipeline processed and delivered the records exactly as designed; the records themselves were simply wrong.
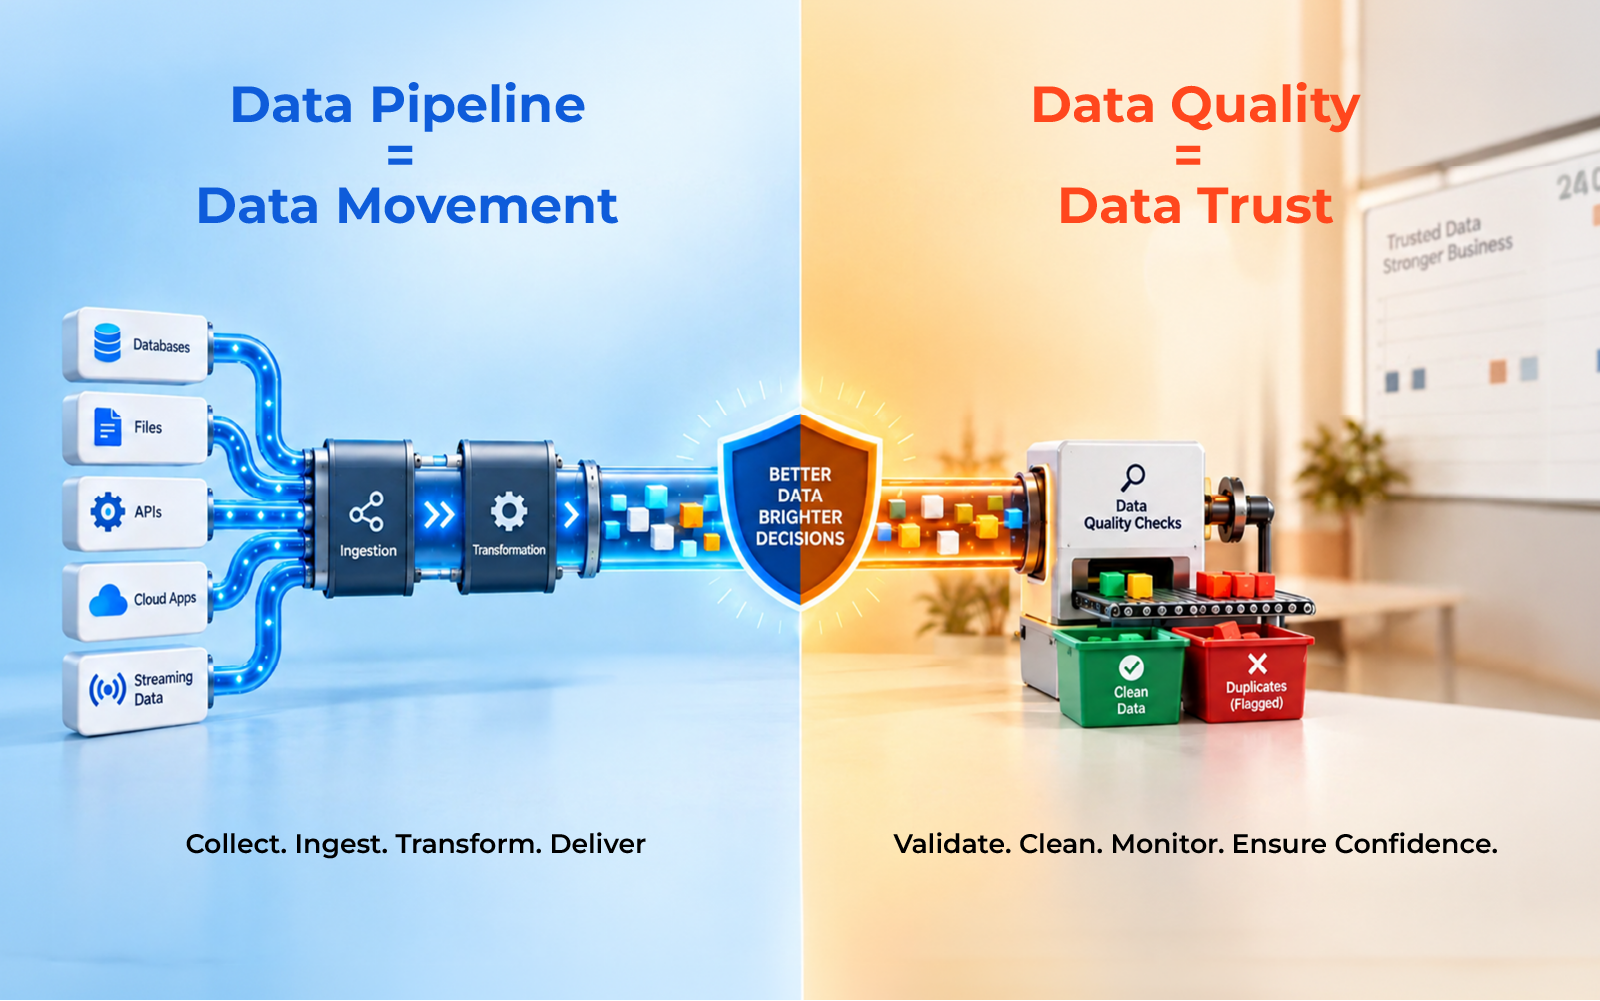
A data pipeline focuses on moving and transforming information reliably. Data quality focuses on whether that information is accurate, complete, consistent, valid, and trustworthy enough for its intended use. Both work together: the pipeline determines whether data gets where it needs to go, and quality controls determine whether the business can trust what arrived.
Key Takeaways
- Data pipelines move, transform, and deliver data between systems.
- Data quality determines whether that data can be trusted once it arrives.
- Pipeline health and data quality require different metrics and different controls.
- Reliable data environments combine strong pipelines with automated quality checks and clear recovery processes when something breaks.
What Is a Data Pipeline?
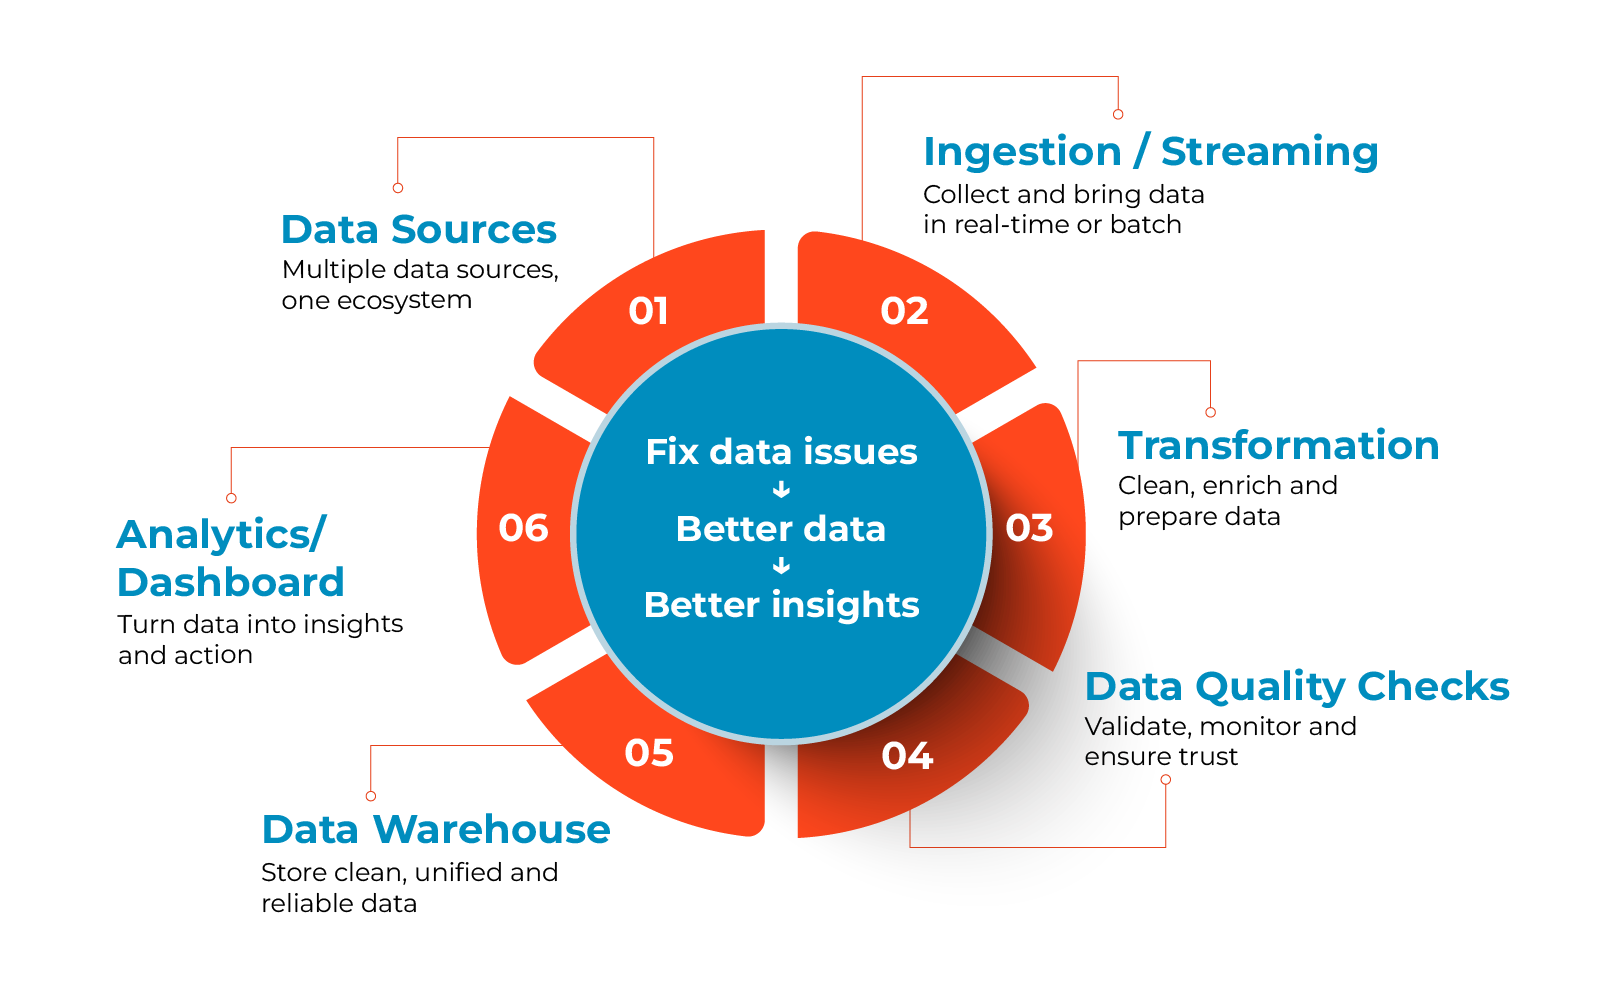
A data pipeline is a series of processes that collect data from one or more sources, transform it, and deliver it to a destination. A typical pipeline collects data from databases, applications, APIs, or event streams; ingests it into a storage or processing environment; transforms and standardizes it; loads the results into a warehouse, lake, or operational system; and delivers it for reporting, analytics, applications, or AI.
For example, a company might collect real-time events through Apache Kafka, transform warehouse data using dbt, and deliver curated datasets to Snowflake or BigQuery.
The primary question for a pipeline is: did the data move through the system reliably and arrive when expected? Pipeline health is therefore measured through job failures, latency, throughput, processing time, and delivery delays.
What Is Data Quality?
Data quality measures whether information is accurate, complete, consistent, valid, unique, and timely enough for its intended purpose. A customer dataset might require unique IDs, valid email addresses, complete records, and consistent values across systems. A financial dataset might require accurate balances, complete transactions, and successful reconciliations.
The primary question is: can the business trust the data it is using?
This matters because data can be technically available but practically unusable. A customer table can load successfully while containing thousands of missing email addresses. A sales table can refresh on schedule while containing duplicate transactions. A product dataset can arrive with every expected row while using invalid category values.
Key Differences at a Glance
| Area | Data Pipeline | Data Quality |
|---|---|---|
| Primary purpose | Moves and transforms data reliably | Ensures data can be trusted |
| Main focus | Movement and delivery | Accuracy and fitness for use |
| Key question | Did the data arrive successfully? | Is the data correct and complete? |
| Common metrics | Latency, throughput, failures | Accuracy, nulls, duplicates, validity |
| Typical controls | Monitoring, retrying, orchestration | Validation, testing, reconciliation |
Pipeline Health vs. Data Quality Metrics
| Metric | Pipeline Health | Data Quality |
|---|---|---|
| Job Success | Did scheduled jobs complete? | Does not confirm output accuracy |
| Latency & Freshness | Was data processed on time? | Is the data current enough for its intended use? |
| Completeness | Did expected records reach the destination? | Are required records and fields present? |
| Duplicates | Were unexpected volume changes detected? | Are duplicate records violating business rules? |
| Validation & Reconciliation | Did data move successfully? | Does it meet business rules and match expected totals? |
A pipeline controls how data moves; quality controls whether the resulting data is trustworthy. Neither substitute for the other.
A Practical Example: When “Nothing Failed” Still Means Something Broke
Consider a customer analytics pipeline that runs successfully every morning. One day, a source-system update changes customer state values from two-letter abbreviations (CA, NY) to full names (California, New York). Nothing technically fails: the records arrive, the transformation completes, and the warehouse refreshes, but a downstream dashboard still filters on the old two-letter codes. Customers from several states silently disappear from the report.
This is a data quality issue, not a pipeline execution failure. A schema or business-rule check applied before the data reached the dashboard would have caught it.
Other common scenarios follow the same pattern; the pipeline runs cleanly, but the output is compromised:
- Duplicate transactions: an API retry creates the same order twice.
- Missing customer data: a source application stops sending phone numbers.
- Schema changes: a source system changes a field type without notifying downstream teams.
- Incorrect mappings: a product category gets mapped to the wrong business classification.
- Reconciliation failures: source transaction totals don’t match warehouse totals.
How Tools Fit into the Data Lifecycle
Rather than a single left-to-right sequence, it’s more useful to think of the tools in four functional groups: tools that move data (Airflow, Kafka), tools that shape it (dbt), tools that trust it (Great Expectations, Bigeye, Datafold), and tools that use it (Snowflake, BigQuery, and the BI/AI layer on top). Choosing between them within a group usually comes down to what you’re optimizing for: batch vs. streaming, build-it-yourself flexibility vs. managed simplicity, or engineering-first vs. analyst-friendly workflows.
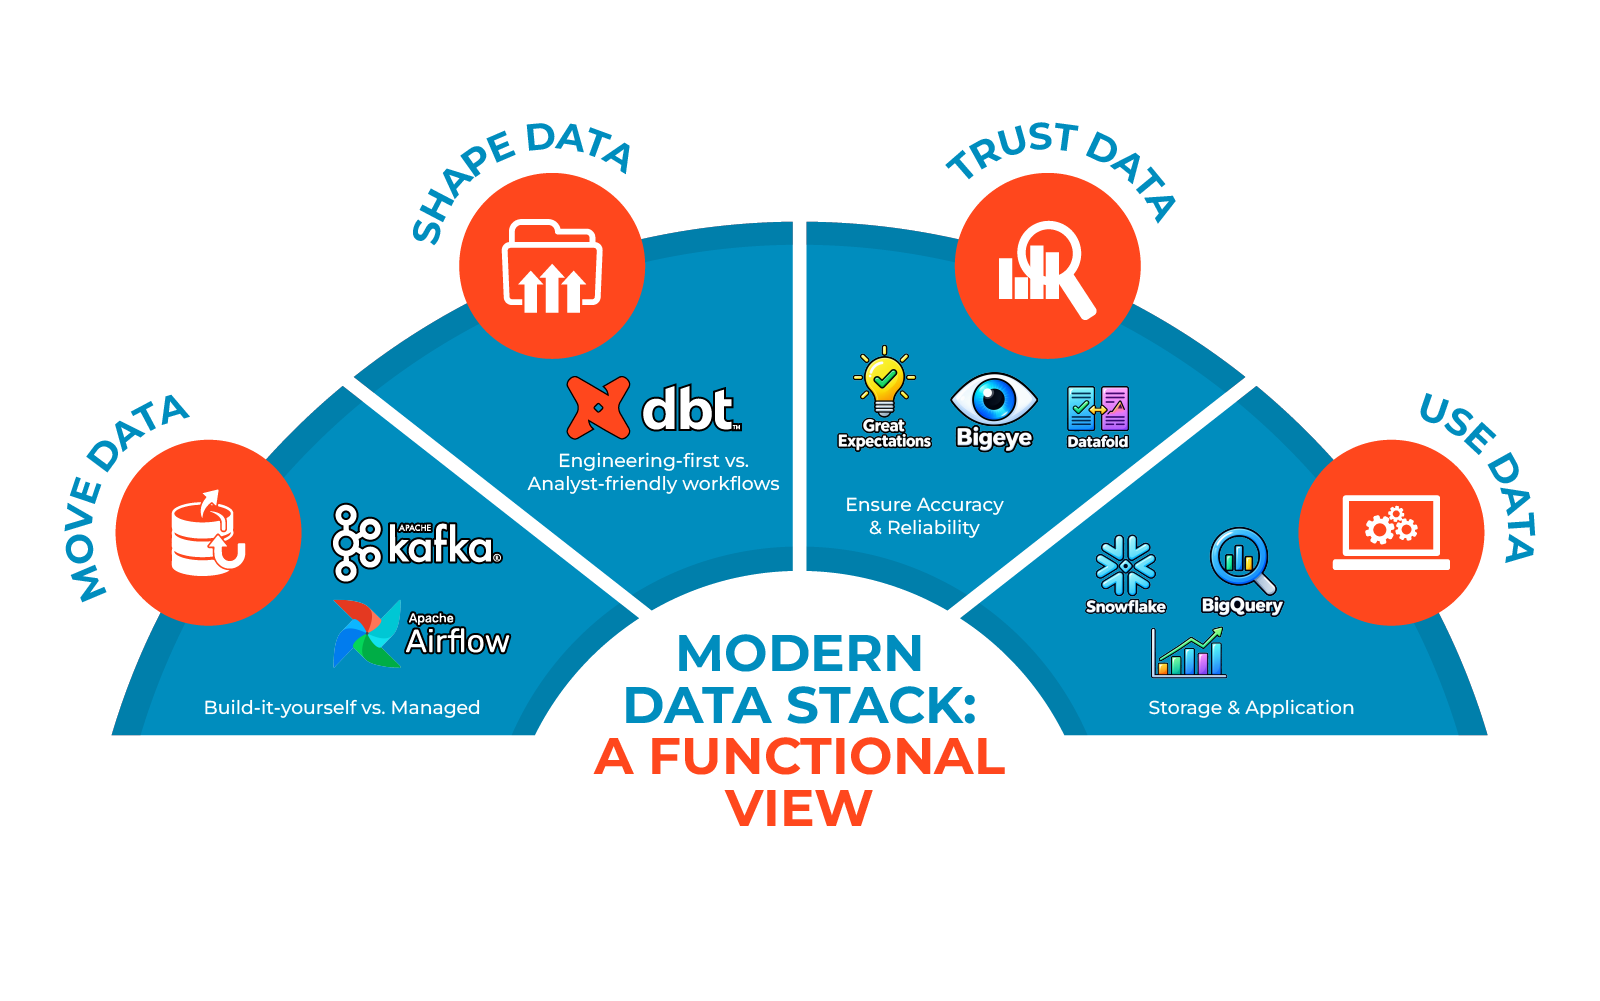
Ingestion and orchestration. Apache Airflow, AWS Glue, and Azure Data Factory schedule workflows and coordinate dependencies between processing steps. Airflow is the common choice when a team wants full control over DAGs and is comfortable managing the infrastructure; Glue and Data Factory trade some of that flexibility for tighter integration with AWS and Azure respectively, which reduces operational overhead for teams already committed to one cloud.
Streaming. Apache Kafka is the default when data needs to be processed continuously, for use cases like fraud detection, live inventory, and event-driven applications, rather than on a batch schedule. The trade-off is operational complexity: Kafka clusters require real investment in monitoring and tuning, so teams without a genuine low-latency requirement are often better served by simpler batch orchestration.
Transformation. dbt has become the standard for turning raw warehouse data into structured, analytics-ready tables, largely because it lets analysts write transformations in SQL while still getting version control, testing, and documentation. Its limitation is scope: dbt transforms data already inside the warehouse, so it doesn’t replace ingestion or streaming tools; it sits downstream of them.
Data quality. Great Expectations and Soda automate checks for missing values, duplicates, invalid records, and custom business rules. Great Expectations tends to suit teams that want highly customizable, code-first validation embedded in pipelines; Soda leans toward faster setup with a lighter learning curve, which matters more for teams that want quality checks running quickly than ones that need deep customization.
Data observability. Monte Carlo, Bigeye, and Datafold monitor unexpected changes in freshness, schema, volume, and other health signals, often without requiring rules to be hand-written in advance. This is the key difference from the “data quality” category above: observability tools are designed to catch problems you didn’t think to test for, while quality tools enforce rules you already know that matter. Mature data environments typically use both: explicit tests for known business rules, plus observability for the unknowns.
The exact tools vary by organization and budget. What matters is having the right kind of control (orchestration, transformation, validation, observability) at the right point in the lifecycle, not necessarily the specific vendor.
How to Improve Pipeline Reliability and Data Quality Together
- Define what “good data” means for each dataset. A marketing dataset may tolerate a small percentage of missing phone numbers; a financial transaction dataset may require near-complete records and exact reconciliation. Set quality requirements based on business risk and intended use, not a single blanket standard.
- Test data at critical boundaries. Run checks as data enters the platform, leaves a transformation, enters a critical warehouse table, or moves into a reporting system, rather than waiting for a dashboard to expose the problem downstream.
- Monitor data, not just jobs. A pipeline dashboard confirms a job succeeded. A stronger monitoring strategy also asks whether row counts changed unexpectedly, null values spiked, duplicates appeared, the schema shifted, or totals stopped reconciling with the source.
- Make quality checks actionable. An alert without an owner or a defined response is just noise. A working pattern looks like: duplicate order IDs detected → stop downstream processing → identify affected records → correct or quarantine them → rerun the affected process.
- Build recovery without creating new problems. This is where a lot of “healthy pipeline, bad data” incidents originate, not from the initial failure, but from how the system recovers from it. Three concepts do most of the work here:
-
- Idempotent processing means running the same operation twice produces the same result as running it once. Without this, a retried job after a timeout can insert a record a second time, even though the first attempt succeeded, which is exactly how the duplicate-order scenario in the introduction happens in practice.
- Checkpoints record how far a pipeline got before it failed, so a retry resumes from that point instead of reprocessing (and potentially re-inserting) everything from the start.
- Reconciliation is a closing check that compares totals or record counts between source and destination after processing, catching silent mismatches that neither a job-success flag nor a schema check would notice on its own.
Used together, these three controls mean a failure and retry can be resolved without becoming a new data quality incident, which is usually the more likely failure mode than the original outage itself.
Frequently Asked Questions
Yes. A successful pipeline run confirms that processing completed, but it does not confirm that the resulting data is accurate, complete, or fit for its intended purpose.
Yes. Manual processes can produce high-quality data on a small scale, but they become increasingly difficult to sustain as data volume, frequency, and the number of sources grow.
Both. Pipeline monitoring tracks whether data arrives within the expected timeframe, while data-quality monitoring evaluates whether the data is current enough for its intended use.
Business or domain owners should define what correct data means for a particular dataset. Data and engineering teams can then implement and automate checks against those business requirements.
No. Data-quality requirements should be aligned with the dataset's purpose, business importance, and downstream risk. Critical datasets may require more comprehensive checks than low-risk or exploratory data.
Conclusion
A green pipeline dashboard tells you the system worked. It doesn’t tell you the data is right, and the two failures look identical until someone downstream catches the discrepancy, usually the hard way.
The fix isn’t choosing between pipeline monitoring and data quality checks; it’s building both at the specific boundaries where each one has a job to do, with retries designed to resolve failures instead of quietly compounding them. If you’re auditing your own stack, a reasonable starting point is this: pick your single most business-critical table, and check whether you currently have a quality test (not just a job-success check) at the point where data lands in it. If the answer is no, that’s where to start.

Saurabh Tikekar | Data Engineer
Tired of broken scrapers and messy data?
Let us handle the complexity while you focus on insights.